More than half of that state.db was copies of messages you already pruned
Your laptop fan has started coming on during idle work. Backups take longer every week. hermes sessions stats reports a database several gigabytes wide — but your session list does not look like several gigabytes. Most conversations are a dozen turns, and their history was compressed long ago. So where did the space go?
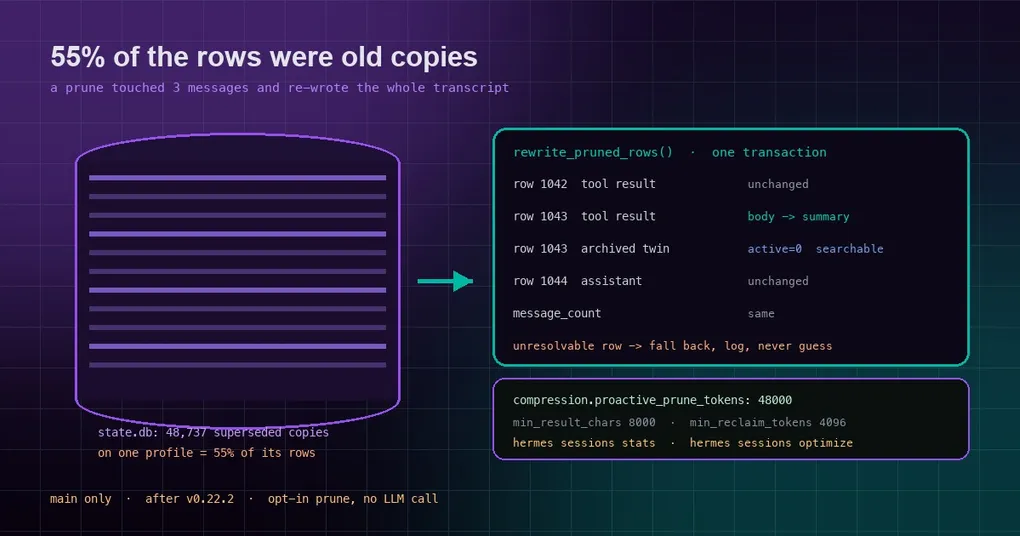
The answer is a little counter-intuitive: it went to the old messages you already pruned. Their full bodies got copied into “archived” twins, over and over. On one install with the optional prune enabled, a single profile accumulated 31,930 of those copies; a second profile had 48,737 — 55% of all its rows.
What prune is actually doing
Hermes has an opt-in feature called proactive prune (compression.proactive_prune_tokens, off by default). It is deliberately modest: when re-sent history grows past your token threshold, it replaces old, bulky tool results — terminal dumps, file reads, web extracts — with short summaries. No model call involved.
The important part: a prune edits the body of a few existing messages. It never adds a message, drops one, or reorders them. From the data’s point of view it is a local edit.
The old commit path disagreed. Every commit went through the full archive-and-compact writer: archive every active row, then re-insert the whole list.
You change three messages; the database gains one copy of the entire transcript.
Once or twice is nothing. But prune fires repeatedly in a long session, and the copies stack up: each one is “the full history as it looked then”, and most of that content becomes the next copy’s source material. That is why the file grows much faster than your conversations do.
The measured numbers
Not estimates — these come from the tracking issue:
| Observation | Value |
|---|---|
| Expired copies, first profile | 31,930 rows |
| Expired copies, second profile | 48,737 rows |
| Share of that profile’s rows | 55% |
| Trigger | proactive prune enabled (example config proactive_prune_tokens: 12000) |
Half of that database was doing nothing but making reads, writes, backups and the full-text index slower.
What changed: rewrite in place
The new commit primitive is SessionDB.rewrite_pruned_rows(session_id, changes, model_config_patch=...), and it runs in a single transaction:
- Name the row. Resolve by
_row_idfirst; otherwise bytool_call_id(tool results) or the tool-call id list an assistant turn carries — unique within a session; otherwise only the single active row with the same role and the same stored content. - Prove it still holds the original. Same role, same tool call id, same call ids, and for tool rows the same stored body. Any mismatch aborts the in-place path.
- Leave one archived twin of its pre-prune self (
active=0, compacted=1), so the demoted full body stays searchable exactly as before. Compaction still does not mean data loss. - Take the changed columns under its own id and merge the rearm patch into
model_config.
Unchanged rows, model order, row ids and concurrently appended rows are never touched. The existing messages_fts_update and messages_display_identity_update triggers keep the full-text and display indexes consistent, and message_count is unchanged because no row enters or leaves the live set.
One detail worth trusting: when the row cannot be named exactly — merged _absorbed_row_ids, zero or several matches, an inactive row, a user row, a body that already changed — it does not guess. It raises PruneRowUnresolvedError before any write, logs it at INFO, and falls back to the old archive-and-compact path. Slower, but correct.
Using it, and checking your own store
1. Find out whether prune is on.
hermes config get compression.proactive_prune_tokens0 (or “Config key not set”) means off, and this mechanism is not what grew your database. To enable it, all three keys live under compression::
compression:
  proactive_prune_tokens: 48000        # 0 = off; 48000 is a reasonable start
  proactive_prune_min_result_chars: 8000   # results smaller than this are left alone
  proactive_prune_min_reclaim_tokens: 4096 # do not commit unless it reclaims this much
2. Measure the store.
hermes sessions stats
du -sh ~/.hermes/state.db
(Non-default profiles keep their data under their own profile directory.)
3. Reclaim space — two different operations, do not confuse them.
hermes sessions optimize          # merge FTS5 segments + VACUUM; no session data changes
hermes sessions optimize-storage  # migrate the full-text index to the compact v23 layout
optimize reclaims free pages; optimize-storage changes the index layout and can reclaim a large fraction on big databases. Neither one deletes old copies for you — what to archive or delete is still your retention decision. The fix stops new copies from being created; it does not clean up the ones already there. Existing rows stay until you archive or delete sessions on your own schedule.
One honest status note: the change merged to main on October 18, 2026, after v0.22.2 shipped on October 15, so the current release does not include it. New prunes start using the in-place path after your next hermes update.
Why this kind of growth stays invisible
Three reasons stack up.
- It is a by-product of something correct. Archive-and-reinsert guaranteed each commit was a complete, consistent snapshot. There was no logic bug — the cost was just booked to disk.
- Metrics do not show it. Session count unchanged, message count unchanged, UI fine. Only file size and I/O slowly degrade.
- It scales with usage. The more long sessions and large tool outputs you run, the faster it grows — and heavy users are the least likely to notice, because their machines are busy anyway.
This is not database corruption, and the two should not be mixed up: a broken schema or vanished session has its own repair path, covered in recovering a damaged state.db. Here the data was perfectly healthy — there was simply too much of it.
The general lesson
“Update in place” and “rewrite the whole thing” are functionally equivalent and completely different in cost. Many systems choose the rewrite because it is simple and cannot leave a half-written state; the price is copying all data for every small edit. Put that on a hot path — every few turns — and the price accumulates faster than you would expect.
The test is blunt: if you changed one row, should you be writing N? If not, that path eventually becomes a capacity problem. The fix rarely needs a new storage engine; usually it just needs the caller to recognise an in-place update — here, naming the exact row by its tool-call identity and verifying nothing else moved.
To control context and history size more deliberately, two related posts go deeper: the lean-tail compression strategy covers what survives a compaction, and rebuilding the prompt after compaction covers what the model sees afterwards. If you manage sessions from a shell, the hermes sessions reference lists every subcommand and filter.
Summary
- Symptom:
state.dbfar larger than your conversation volume; slow backups, heavy I/O, odd row counts inhermes sessions stats. - Cause: every proactive-prune commit archived all active rows and re-inserted the whole list — 48,737 superseded copies on one profile, 55% of its rows.
- Fix:
rewrite_pruned_rows()updates only the changed columns, keeps one searchable archived twin, and falls back safely when a row cannot be named exactly. - Today: check the switch with
hermes config get compression.proactive_prune_tokens, size the store withhermes sessions stats, reclaim withhermes sessions optimize, and update to get the new commit path.